

构建 SQL 数据库问答系统需要执行模型生成的 SQL 查询。这样做存在固有风险。请确保数据库连接权限始终尽可能严格地限制在智能体所需范围内。这可以降低构建模型驱动系统的风险,但无法完全消除风险。
概念
我们将介绍以下概念:设置
安装
pip install langchain langgraph
LangSmith
设置 LangSmith,以便检查你的链或智能体内部正在发生什么。然后设置以下环境变量:export LANGSMITH_TRACING="true"
export LANGSMITH_API_KEY="..."
1. 选择一个 LLM
选择一个支持 tool-calling 的模型:- OpenAI
- Anthropic
- Azure
- Google Gemini
- AWS Bedrock
- HuggingFace
- OpenRouter
👉 阅读 OpenAI 聊天模型集成文档
pip install -U "langchain[openai]"
import os
from langchain.chat_models import init_chat_model

os.environ["OPENAI_API_KEY"] = "sk-..."

model = init_chat_model("gpt-5.5")
import os
from langchain_openai import ChatOpenAI

os.environ["OPENAI_API_KEY"] = "sk-..."

model = ChatOpenAI(model="gpt-5.5")
👉 阅读 Anthropic 聊天模型集成文档
pip install -U "langchain[anthropic]"
import os
from langchain.chat_models import init_chat_model

os.environ["ANTHROPIC_API_KEY"] = "sk-..."

model = init_chat_model("claude-sonnet-4-6")
import os
from langchain_anthropic import ChatAnthropic

os.environ["ANTHROPIC_API_KEY"] = "sk-..."

model = ChatAnthropic(model="claude-sonnet-4-6")
👉 阅读 Azure 聊天模型集成文档
pip install -U "langchain[openai]"
import os
from langchain.chat_models import init_chat_model

os.environ["AZURE_OPENAI_API_KEY"] = "..."
os.environ["AZURE_OPENAI_ENDPOINT"] = "..."
os.environ["OPENAI_API_VERSION"] = "2025-03-01-preview"

model = init_chat_model(
    "azure_openai:gpt-5.5",
    azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"],
)
import os
from langchain_openai import AzureChatOpenAI

os.environ["AZURE_OPENAI_API_KEY"] = "..."
os.environ["AZURE_OPENAI_ENDPOINT"] = "..."
os.environ["OPENAI_API_VERSION"] = "2025-03-01-preview"

model = AzureChatOpenAI(
    model="gpt-5.5",
    azure_deployment=os.environ["AZURE_OPENAI_DEPLOYMENT_NAME"]
)
👉 阅读 Google GenAI 聊天模型集成文档
pip install -U "langchain[google-genai]"
import os
from langchain.chat_models import init_chat_model

os.environ["GOOGLE_API_KEY"] = "..."

model = init_chat_model("google_genai:gemini-2.5-flash-lite")
import os
from langchain_google_genai import ChatGoogleGenerativeAI

os.environ["GOOGLE_API_KEY"] = "..."

model = ChatGoogleGenerativeAI(model="gemini-2.5-flash-lite")
👉 阅读 AWS Bedrock 聊天模型集成文档
pip install -U "langchain[aws]"
from langchain.chat_models import init_chat_model

# 请按照此页面的步骤配置您的凭证:
# https://docs.aws.amazon.com/bedrock/latest/userguide/getting-started.html

model = init_chat_model(
    "us.anthropic.claude-sonnet-4-6",
    model_provider="bedrock_converse",
)
from langchain_aws import ChatBedrock

model = ChatBedrock(model="us.anthropic.claude-sonnet-4-6")
👉 阅读 HuggingFace 聊天模型集成文档
pip install -U "langchain[huggingface]"
import os
from langchain.chat_models import init_chat_model

os.environ["HUGGINGFACEHUB_API_TOKEN"] = "hf_..."

model = init_chat_model(
    "microsoft/Phi-3-mini-4k-instruct",
    model_provider="huggingface",
    temperature=0.7,
    max_tokens=1024,
)
import os
from langchain_huggingface import ChatHuggingFace, HuggingFaceEndpoint

os.environ["HUGGINGFACEHUB_API_TOKEN"] = "hf_..."

llm = HuggingFaceEndpoint(
    repo_id="microsoft/Phi-3-mini-4k-instruct",
    temperature=0.7,
    max_length=1024,
)
model = ChatHuggingFace(llm=llm)
👉 阅读 OpenRouter 聊天模型集成文档
pip install -U "langchain-openrouter"
import os
from langchain.chat_models import init_chat_model

os.environ["OPENROUTER_API_KEY"] = "sk-..."

model = init_chat_model(
    "auto",
    model_provider="openrouter",
)
import os
from langchain_openrouter import ChatOpenRouter

os.environ["OPENROUTER_API_KEY"] = "sk-..."

model = ChatOpenRouter(model="auto")
2. 配置数据库
在本教程中,你将创建一个 SQLite 数据库。SQLite 是一个轻量级数据库,易于设置和使用。我们将加载chinook 数据库,这是一个表示数字媒体商店的示例数据库。
为方便起见,我们已将数据库(Chinook.db)托管在一个公开的 GCS 存储桶中。
import pathlib
import requests

url = "https://storage.googleapis.com/benchmarks-artifacts/chinook/Chinook.db"
local_path = pathlib.Path("Chinook.db")

if local_path.exists():
    print(f"{local_path} already exists, skipping download.")
else:
    response = requests.get(url, timeout=60)
    if response.status_code == 200:
        local_path.write_bytes(response.content)
        print(f"File downloaded and saved as {local_path}")
    else:
        print(f"Failed to download the file. Status code: {response.status_code}")
sqlite3 模块与数据库交互:
import sqlite3

con = sqlite3.connect("Chinook.db")
cursor = con.cursor()

cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
tables = [row[0] for row in cursor.fetchall() if not row[0].startswith("sqlite_")]

print("Dialect: sqlite")
print(f"Available tables: {tables}")

cursor.execute("SELECT * FROM Artist LIMIT 5;")
print(f"Sample output: {cursor.fetchall()}")
con.close()
Dialect: sqlite
Available tables: ['Album', 'Artist', 'Customer', 'Employee', 'Genre', 'Invoice', 'InvoiceLine', 'MediaType', 'Playlist', 'PlaylistTrack', 'Track']
Sample output: [(1, 'AC/DC'), (2, 'Accept'), (3, 'Aerosmith'), (4, 'Alanis Morissette'), (5, 'Alice In Chains')]
3. 添加用于数据库交互的工具
以下数据库工具只是用于演示的最小封装。它们并不用于保障安全,也不适合在生产环境中使用。请使用范围尽可能小的数据库权限,并在执行模型生成的 SQL 之前添加应用特定的验证。
langchain.tools 的 @tool 装饰器,将数据库 tools 实现为轻量封装:
import sqlite3
from langchain.tools import tool

# 以下是用于演示的最小工具集。


@tool
def sql_db_list_tables() -> str:
    """输入是一个空字符串,输出是数据库中以逗号分隔的表名列表。"""
    con = sqlite3.connect("Chinook.db")
    try:
        cursor = con.cursor()
        cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
        tables = [
            row[0]
            for row in cursor.fetchall()
            if not row[0].startswith("sqlite_")
        ]
        return ", ".join(tables)
    finally:
        con.close()


@tool
def sql_db_schema(table_names: str) -> str:
    """此工具的输入是一个以逗号分隔的表名列表,输出是这些表的 schema 和示例行。
    请务必先调用 sql_db_list_tables 确保这些表实际存在!
    示例输入: table1, table2, table3"""
    con = sqlite3.connect("Chinook.db")
    try:
        cursor = con.cursor()
        cursor.execute("SELECT name FROM sqlite_master WHERE type='table';")
        valid_tables = {
            row[0] for row in cursor.fetchall() if not row[0].startswith("sqlite_")
        }
        results = []
        for table in table_names.split(","):
            table = table.strip()
            if table not in valid_tables:
                results.append(
                    f"Error: table_names {{{table!r}}} not found in database"
                )
                continue
            cursor.execute(
                "SELECT sql FROM sqlite_master WHERE type='table' AND name=?;",
                (table,),
            )
            schema_row = cursor.fetchone()
            if schema_row:
                results.append(schema_row[0])
                try:
                    quoted_table = '"' + table.replace('"', '""') + '"'
                    cursor.execute(f"SELECT * FROM {quoted_table} LIMIT 3;")
                    rows = cursor.fetchall()
                    if rows:
                        col_names = [description[0] for description in cursor.description]
                        results.append(
                            f"/*\n3 rows from {table} table:\n"
                            + "\t".join(col_names)
                            + "\n"
                            + "\n".join(
                                "\t".join(str(x) for x in row) for row in rows
                            )
                            + "\n*/"
                        )
                except Exception as e:
                    results.append(f"Error fetching sample rows: {e}")
        return "\n\n".join(results)
    finally:
        con.close()


@tool
def sql_db_query(query: str) -> str:
    """此工具的输入是一个详细且正确的 SQL 查询语句,输出是数据库的结果。
    如果查询不正确,将返回一条错误消息。
    如果返回错误,请重写查询,检查查询语句,并再次尝试。
    如果遇到 `Unknown column 'xxxx' in 'field list'` 问题,请使用 sql_db_schema 查询正确的表字段。"""
    con = sqlite3.connect("Chinook.db")
    try:
        cursor = con.cursor()
        cursor.execute(query)
        res = cursor.fetchall()
        return str(res)
    except Exception as e:
        return f"Error: {e}"
    finally:
        con.close()


tools = [sql_db_list_tables, sql_db_schema, sql_db_query]

# 使用一个不同的循环变量,以避免遮蔽后续重用的 `tool` 装饰器(用于包装查询工具供人工审查)。
for t in tools:
    print(f"{t.name}: {t.description}\n")
sql_db_list_tables: Input is an empty string, output is a comma-separated list of tables in the database.

sql_db_schema: Input to this tool is a comma-separated list of tables, output is the schema and sample rows for those tables.
    Be sure that the tables actually exist by calling sql_db_list_tables first!
    Example Input: table1, table2, table3

sql_db_query: Input to this tool is a detailed and correct SQL query, output is a result from the database.
    If the query is not correct, an error message will be returned.
    If an error is returned, rewrite the query, check the query, and try again.
    If you encounter an issue with Unknown column 'xxxx' in 'field list', use sql_db_schema to query the correct table fields.
4. 定义应用步骤
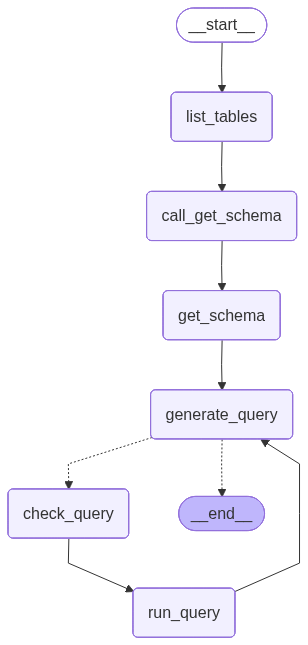
我们为以下步骤构建专用节点:- 列出数据库表
- 调用 “get schema” 工具
- 生成查询
- 检查查询
from typing import Literal

from langchain.messages import AIMessage
from langchain_core.runnables import RunnableConfig
from langgraph.graph import END, START, MessagesState, StateGraph
from langgraph.prebuilt import ToolNode

get_schema_tool = next(tool for tool in tools if tool.name == "sql_db_schema")
get_schema_node = ToolNode([get_schema_tool], name="get_schema")

run_query_tool = next(tool for tool in tools if tool.name == "sql_db_query")
run_query_node = ToolNode([run_query_tool], name="run_query")


# Example: create a predetermined tool call
def list_tables(state: MessagesState):
    tool_call = {
        "name": "sql_db_list_tables",
        "args": {},
        "id": "abc123",
        "type": "tool_call",
    }
    tool_call_message = AIMessage(content="", tool_calls=[tool_call])

    list_tables_tool = next(tool for tool in tools if tool.name == "sql_db_list_tables")
    tool_message = list_tables_tool.invoke(tool_call)
    response = AIMessage(f"Available tables: {tool_message.content}")

    return {"messages": [tool_call_message, tool_message, response]}


# Example: force a model to create a tool call
def call_get_schema(state: MessagesState):
    # Note that LangChain enforces that all models accept `tool_choice="any"`
    # as well as `tool_choice=<string name of tool>`.
    llm_with_tools = model.bind_tools([get_schema_tool], tool_choice="any")
    response = llm_with_tools.invoke(state["messages"])

    return {"messages": [response]}


generate_query_system_prompt = """
You are an agent designed to interact with a SQL database.
Given an input question, create a syntactically correct {dialect} query to run,
then look at the results of the query and return the answer. Unless the user
specifies a specific number of examples they wish to obtain, always limit your
query to at most {top_k} results.

You can order the results by a relevant column to return the most interesting
examples in the database. Never query for all the columns from a specific table,
only ask for the relevant columns given the question.

DO NOT make any DML statements (INSERT, UPDATE, DELETE, DROP etc.) to the database.
""".format(
    dialect="sqlite",
    top_k=5,
)


def generate_query(state: MessagesState):
    system_message = {
        "role": "system",
        "content": generate_query_system_prompt,
    }
    # We do not force a tool call here, to allow the model to
    # respond naturally when it obtains the solution.
    llm_with_tools = model.bind_tools([run_query_tool])
    response = llm_with_tools.invoke([system_message] + state["messages"])

    return {"messages": [response]}


check_query_system_prompt = """
You are a SQL expert with a strong attention to detail.
Double check the {dialect} query for common mistakes, including:
- Using NOT IN with NULL values
- Using UNION when UNION ALL should have been used
- Using BETWEEN for exclusive ranges
- Data type mismatch in predicates
- Properly quoting identifiers
- Using the correct number of arguments for functions
- Casting to the correct data type
- Using the proper columns for joins

If there are any of the above mistakes, rewrite the query. If there are no mistakes,
just reproduce the original query.

You will call the appropriate tool to execute the query after running this check.
""".format(dialect="sqlite")


def check_query(state: MessagesState):
    system_message = {
        "role": "system",
        "content": check_query_system_prompt,
    }

    # Generate an artificial user message to check
    tool_call = state["messages"][-1].tool_calls[0]
    user_message = {"role": "user", "content": tool_call["args"]["query"]}
    llm_with_tools = model.bind_tools([run_query_tool], tool_choice="any")
    response = llm_with_tools.invoke([system_message, user_message])
    response.id = state["messages"][-1].id

    return {"messages": [response]}
5. 实现智能体
现在我们可以使用 Graph API 将这些步骤组装成一个工作流。我们在查询生成步骤定义一个 条件边:如果生成了查询,则路由到查询检查器;如果不存在工具调用,则结束,这表示 LLM 已经对查询给出了响应。def should_continue(state: MessagesState) -> Literal[END, "check_query"]:
messages = state["messages"]
last_message = messages[-1]
if not last_message.tool_calls:
return END
else:
return "check_query"
builder = StateGraph(MessagesState)
builder.add_node(list_tables)
builder.add_node(call_get_schema)
builder.add_node(get_schema_node, "get_schema")
builder.add_node(generate_query)
builder.add_node(check_query)
builder.add_node(run_query_node, "run_query")
builder.add_edge(START, "list_tables")
builder.add_edge("list_tables", "call_get_schema")
builder.add_edge("call_get_schema", "get_schema")
builder.add_edge("get_schema", "generate_query")
builder.add_conditional_edges(
"generate_query",
should_continue,
)
builder.add_edge("check_query", "run_query")
builder.add_edge("run_query", "generate_query")
agent = builder.compile()
import pathlib

pathlib.Path("graph.png").write_bytes(agent.get_graph().draw_mermaid_png())
 现在我们可以调用该图:
question = "平均曲目时长最长的音乐类型是哪个?"

stream = agent.stream_events(
    {"messages": [{"role": "user", "content": question}]},
    version="v3",
)
for message in stream.messages:
    for token in message.text:
        print(token, end="", flush=True)

final_state = stream.output
================================ Human Message =================================

Which genre on average has the longest tracks?
================================== Ai Message ==================================

Available tables: Album, Artist, Customer, Employee, Genre, Invoice, InvoiceLine, MediaType, Playlist, PlaylistTrack, Track
================================== Ai Message ==================================
Tool Calls:
  sql_db_schema (call_yzje0tj7JK3TEzDx4QnRR3lL)
 Call ID: call_yzje0tj7JK3TEzDx4QnRR3lL
  Args:
    table_names: Genre, Track
================================= Tool Message =================================
Name: sql_db_schema


CREATE TABLE "Genre" (
	"GenreId" INTEGER NOT NULL,
	"Name" NVARCHAR(120),
	PRIMARY KEY ("GenreId")
)

/*
3 rows from Genre table:
GenreId	Name
1	Rock
2	Jazz
3	Metal
*/


CREATE TABLE "Track" (
	"TrackId" INTEGER NOT NULL,
	"Name" NVARCHAR(200) NOT NULL,
	"AlbumId" INTEGER,
	"MediaTypeId" INTEGER NOT NULL,
	"GenreId" INTEGER,
	"Composer" NVARCHAR(220),
	"Milliseconds" INTEGER NOT NULL,
	"Bytes" INTEGER,
	"UnitPrice" NUMERIC(10, 2) NOT NULL,
	PRIMARY KEY ("TrackId"),
	FOREIGN KEY("MediaTypeId") REFERENCES "MediaType" ("MediaTypeId"),
	FOREIGN KEY("GenreId") REFERENCES "Genre" ("GenreId"),
	FOREIGN KEY("AlbumId") REFERENCES "Album" ("AlbumId")
)

/*
3 rows from Track table:
TrackId	Name	AlbumId	MediaTypeId	GenreId	Composer	Milliseconds	Bytes	UnitPrice
1	For Those About To Rock (We Salute You)	1	1	1	Angus Young, Malcolm Young, Brian Johnson	343719	11170334	0.99
2	Balls to the Wall	2	2	1	U. Dirkschneider, W. Hoffmann, H. Frank, P. Baltes, S. Kaufmann, G. Hoffmann	342562	5510424	0.99
3	Fast As a Shark	3	2	1	F. Baltes, S. Kaufman, U. Dirkscneider & W. Hoffman	230619	3990994	0.99
*/
================================== Ai Message ==================================
Tool Calls:
  sql_db_query (call_cb9ApLfZLSq7CWg6jd0im90b)
 Call ID: call_cb9ApLfZLSq7CWg6jd0im90b
  Args:
    query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgMilliseconds FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.GenreId ORDER BY AvgMilliseconds DESC LIMIT 5;
================================== Ai Message ==================================
Tool Calls:
  sql_db_query (call_DMVALfnQ4kJsuF3Yl6jxbeAU)
 Call ID: call_DMVALfnQ4kJsuF3Yl6jxbeAU
  Args:
    query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgMilliseconds FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.GenreId ORDER BY AvgMilliseconds DESC LIMIT 5;
================================= Tool Message =================================
Name: sql_db_query

[('Sci Fi & Fantasy', 2911783.0384615385), ('Science Fiction', 2625549.076923077), ('Drama', 2575283.78125), ('TV Shows', 2145041.0215053763), ('Comedy', 1585263.705882353)]
================================== Ai Message ==================================

The genre with the longest tracks on average is "Sci Fi & Fantasy," with an average track length of approximately 2,911,783 milliseconds. Other genres with relatively long tracks include "Science Fiction," "Drama," "TV Shows," and "Comedy."
请参阅上述运行的 LangSmith trace。
6. 实现人在环路审核
在执行智能体的 SQL 查询之前,先检查是否存在任何非预期操作或低效之处,是一种谨慎的做法。 这里我们利用 LangGraph 的 人在环路 功能,在执行 SQL 查询之前暂停运行,并等待人工审核。使用 LangGraph 的 持久化层,我们可以无限期暂停运行(或者至少在持久化层存活期间暂停)。 让我们将sql_db_query 工具封装到一个接收人工输入的节点中。我们可以使用 interrupt 函数来实现这一点。下面,我们允许输入来批准工具调用、编辑其参数,或提供用户反馈。
from langchain.tools import tool
from langgraph.types import interrupt
from langchain_core.runnables import RunnableConfig


@tool(
    run_query_tool.name,
    description=run_query_tool.description,
    args_schema=run_query_tool.args_schema,
)
def run_query_tool_with_interrupt(config: RunnableConfig, **tool_input):
    request = {
        "action": run_query_tool.name,
        "args": tool_input,
        "description": "Please review the tool call",
    }
    response = interrupt([request])
    # approve the tool call
    if response["type"] == "accept":
        tool_response = run_query_tool.invoke(tool_input, config)
    # update tool call args
    elif response["type"] == "edit":
        tool_input = response["args"]["args"]
        tool_response = run_query_tool.invoke(tool_input, config)
    # respond to the LLM with user feedback
    elif response["type"] == "response":
        user_feedback = response["args"]
        tool_response = user_feedback
    else:
        raise ValueError(f"Unsupported interrupt response type: {response['type']}")

    return tool_response


# Redefine the tool node to use the interrupt version
run_query_node = ToolNode([run_query_tool_with_interrupt], name="run_query")
上述实现遵循更完整的 人在环路 指南中的 tool interrupt example。请参阅该指南了解详细信息和替代方案。
from langgraph.checkpoint.memory import InMemorySaver

def should_continue(state: MessagesState) -> Literal[END, "run_query"]:
    messages = state["messages"]
    last_message = messages[-1]
    if not last_message.tool_calls:
        return END
    else:
        return "run_query"

builder = StateGraph(MessagesState)
builder.add_node(list_tables)
builder.add_node(call_get_schema)
builder.add_node(get_schema_node, "get_schema")
builder.add_node(generate_query)
builder.add_node(run_query_node, "run_query")

builder.add_edge(START, "list_tables")
builder.add_edge("list_tables", "call_get_schema")
builder.add_edge("call_get_schema", "get_schema")
builder.add_edge("get_schema", "generate_query")
builder.add_conditional_edges(
    "generate_query",
    should_continue,
)
builder.add_edge("run_query", "generate_query")

checkpointer = InMemorySaver()
agent = builder.compile(checkpointer=checkpointer)
question = "平均而言,哪种音乐类型的音轨最长?"

stream = agent.stream_events(
    {"messages": [{"role": "user", "content": question}]},
    config,
    version="v3",
)
for message in stream.messages:
    for token in message.text:
        print(token, end="", flush=True)
if stream.interrupted:
    action = stream.interrupts[0]
    print("INTERRUPTED:")
    for request in action.value:
        print(json.dumps(request, indent=2))
...

INTERRUPTED:
{
  "action": "sql_db_query",
  "args": {
    "query": "SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgLength FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.Name ORDER BY AvgLength DESC LIMIT 5;"
  },
  "description": "Please review the tool call"
}
from langgraph.types import Command

stream = agent.stream_events(
    Command(resume={"type": "accept"}),
    # Command(resume={"type": "edit", "args": {"query": "..."}}),
    config,
    version="v3",
)
for message in stream.messages:
    for token in message.text:
        print(token, end="", flush=True)
if stream.interrupted:
    action = stream.interrupts[0]
    print("中断:")
    for request in action.value:
        print(json.dumps(request, indent=2))
================================== Ai Message ==================================
Tool Calls:
  sql_db_query (call_t4yXkD6shwdTPuelXEmY3sAY)
 Call ID: call_t4yXkD6shwdTPuelXEmY3sAY
  Args:
    query: SELECT Genre.Name, AVG(Track.Milliseconds) AS AvgLength FROM Track JOIN Genre ON Track.GenreId = Genre.GenreId GROUP BY Genre.Name ORDER BY AvgLength DESC LIMIT 5;
================================= Tool Message =================================
Name: sql_db_query

[('Sci Fi & Fantasy', 2911783.0384615385), ('Science Fiction', 2625549.076923077), ('Drama', 2575283.78125), ('TV Shows', 2145041.0215053763), ('Comedy', 1585263.705882353)]
================================== Ai Message ==================================

The genre with the longest average track length is "Sci Fi & Fantasy" with an average length of about 2,911,783 milliseconds. Other genres with long average track lengths include "Science Fiction," "Drama," "TV Shows," and "Comedy."
后续步骤
查看 Evaluate a graph 指南,了解如何使用 LangSmith 评估 LangGraph 应用,包括像这样的 SQL 智能体。Connect these docs to Claude, VSCode, and more via MCP for real-time answers.